Generative AI / Retrieval + generation
Enterprise RAG Knowledge Assistant
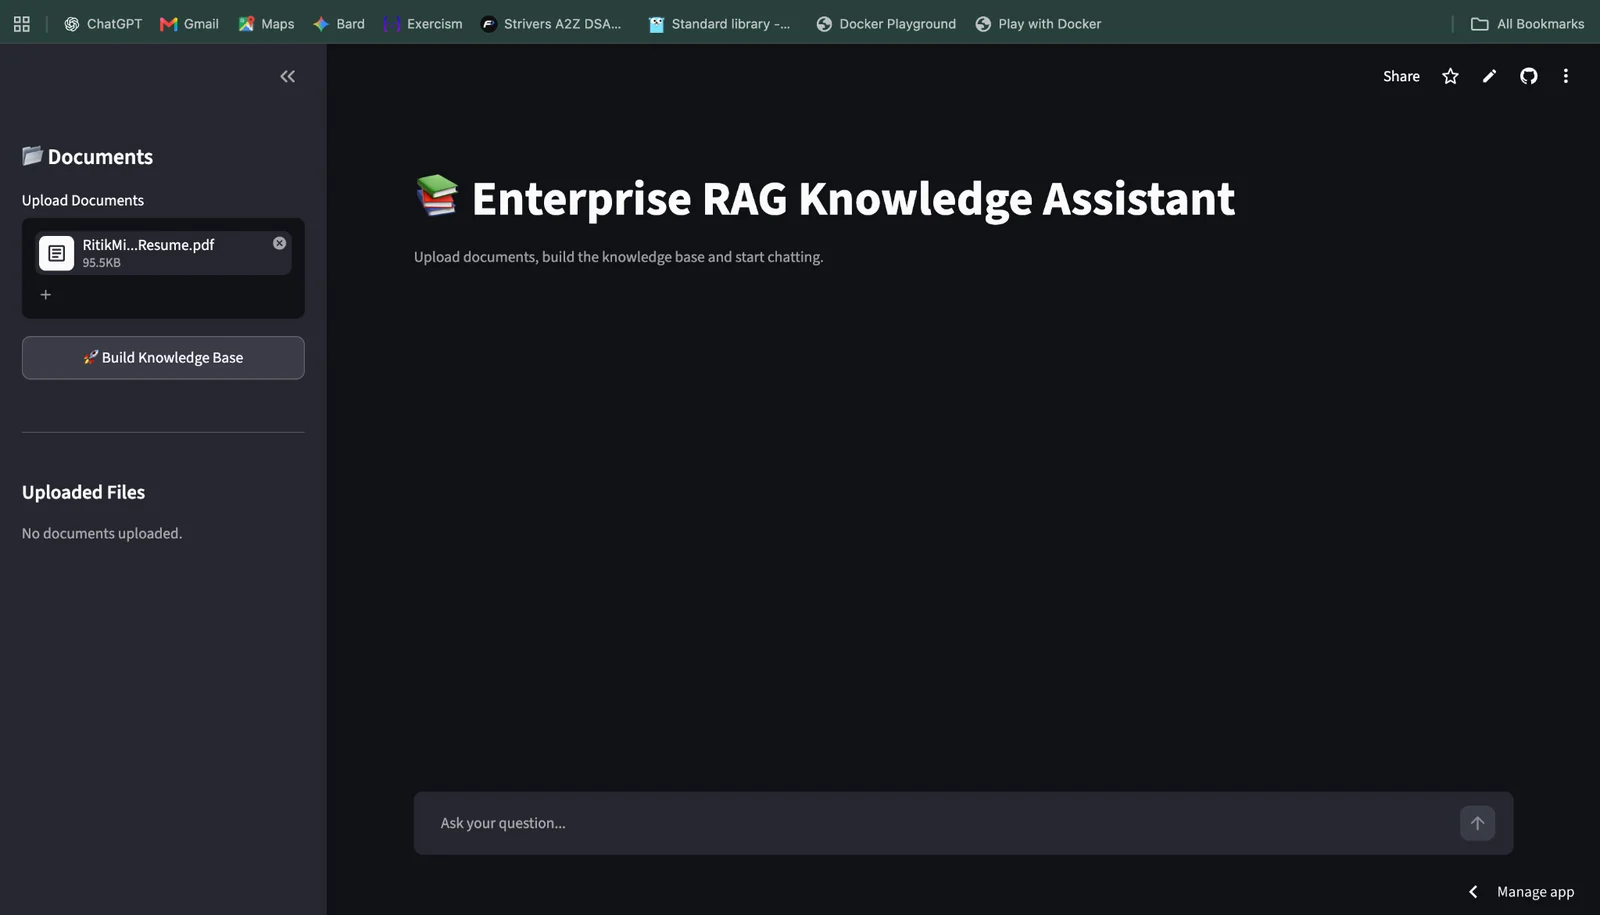
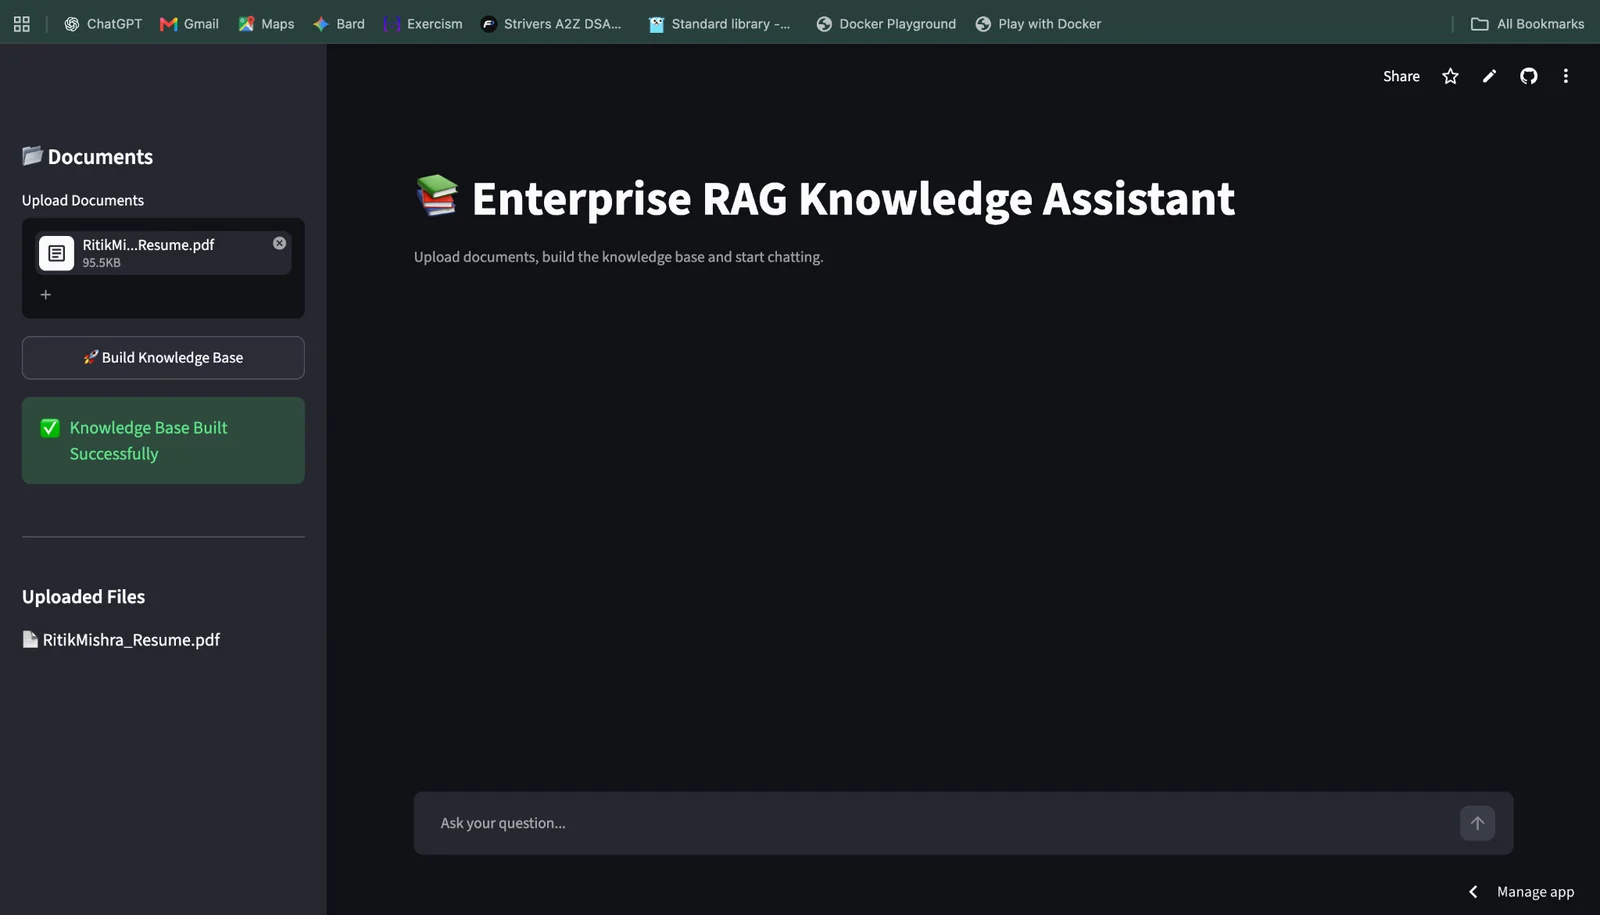
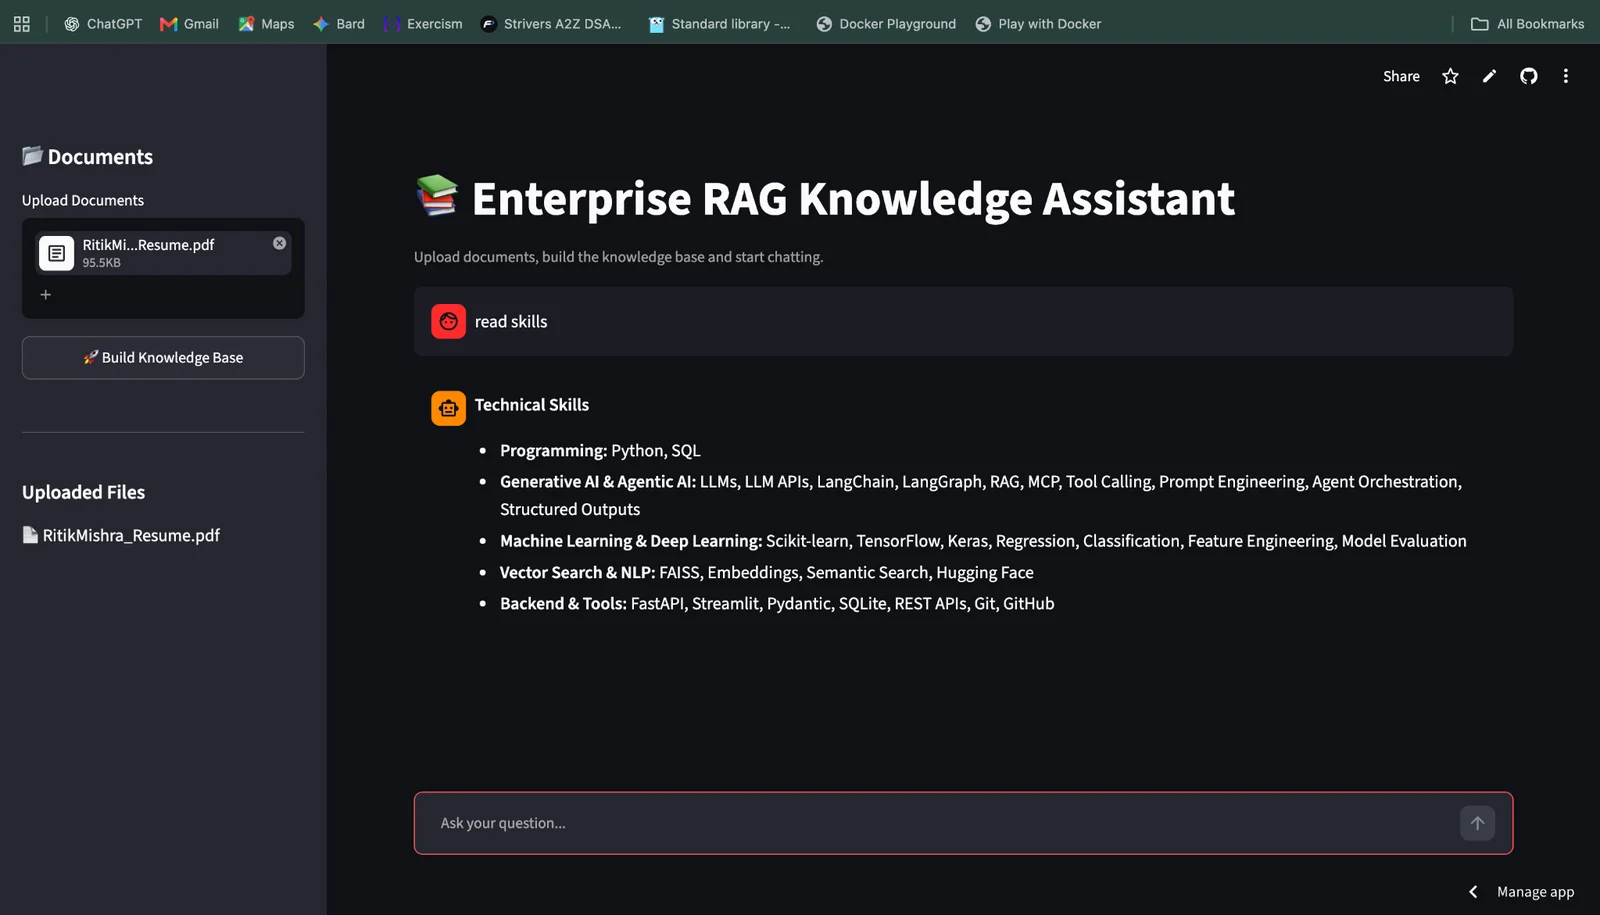
A document-grounded knowledge assistant that ingests common business files, retrieves relevant context, and generates grounded answers.
- Streamlit
- LangGraph
- FAISS
- BAAI/bge-small-en-v1.5
- Gemini 2.5 Flash
Problem
Users need a practical way to ask questions over documents without sending the entire document collection into every model request.
Approach
The application loads supported documents, splits them into overlapping chunks, creates normalized BGE-small-en-v1.5 embeddings on CPU, stores them in FAISS, retrieves the top four matches, and supplies the built context to Gemini 2.5 Flash.
Architecture
Capabilities
- PDF, DOCX, TXT, Markdown, and CSV ingestion
- Chunk size 1000
- Chunk overlap 200
- CPU embeddings
- Normalized embeddings
- Top-k retrieval of 4
- Thread-based state
Problem
Knowledge spread across PDFs, DOCX files, text, Markdown, and CSV needs a focused retrieval workflow before an LLM can answer questions over it.
Solution
The assistant turns uploaded documents into searchable chunks, retrieves the most similar context, and generates an answer using that context.
Document ingestion
The loader supports PDF, DOCX, TXT, Markdown, and CSV documents.
Chunking and embeddings
Documents use a chunk size of 1000 with 200-token overlap. BAAI/bge-small-en-v1.5 creates normalized CPU embeddings.
Retrieval and generation
FAISS retrieves the top four similar chunks. The context builder passes those results to Gemini 2.5 Flash at temperature 0.3.
LangGraph orchestration
The workflow is organized as retrieve, build_context, and generate_answer, with thread-based state.
Challenges and learnings
The implementation makes the ingestion, retrieval, and generation stages explicit so the grounded-answer path remains easy to inspect.